
MaTeLiX ARTIFICIAL INTELLIGENCE - Dashboard
Modernes LLM Training & Finetuning powered by TMP-SYSTEM-SERVICE GmbH
Item Description
Overview
- This code defines a FastAPI-based web server that facilitates:
- Fine-tuning and training of language models (e.g., LLMs like LLaMA)
- Dynamic tokenization optimizations (e.g., N-gram token enhancement)
- Dataset handling, chunking, and streaming
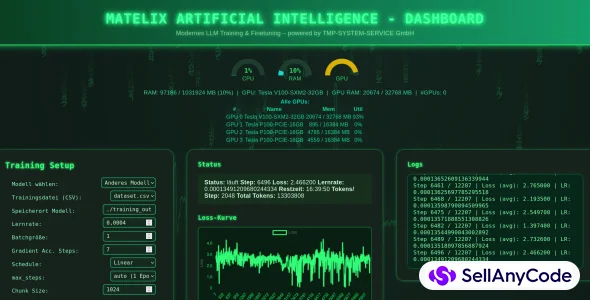
- Monitoring of system resources (RAM, CPU, GPU)
- Live training status, logs, and previewing training chunks
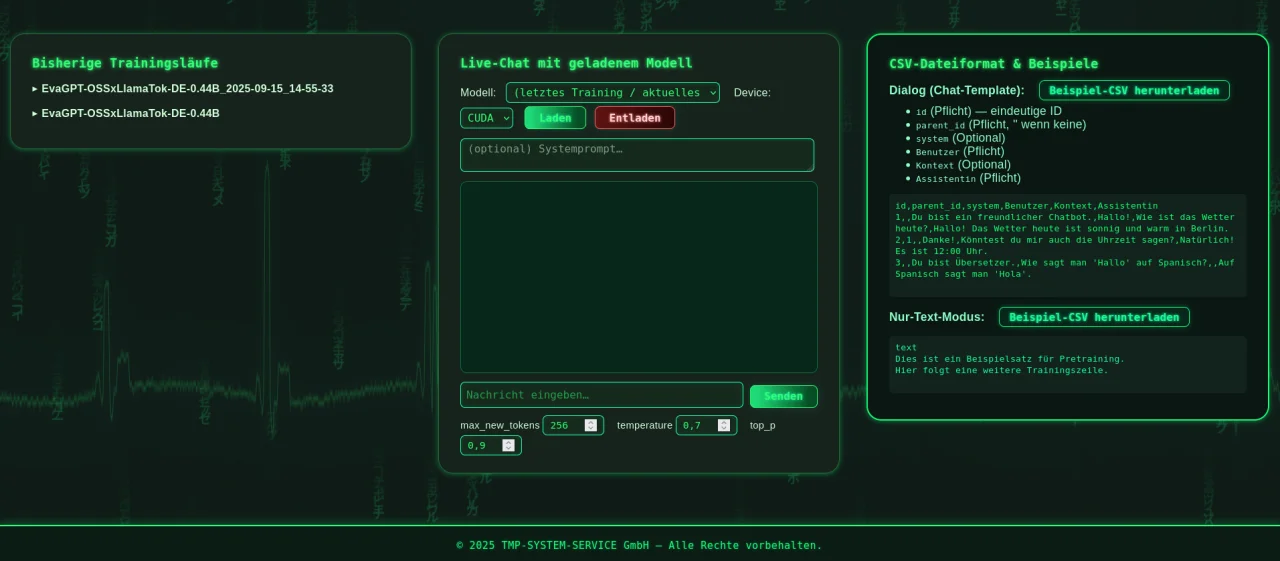
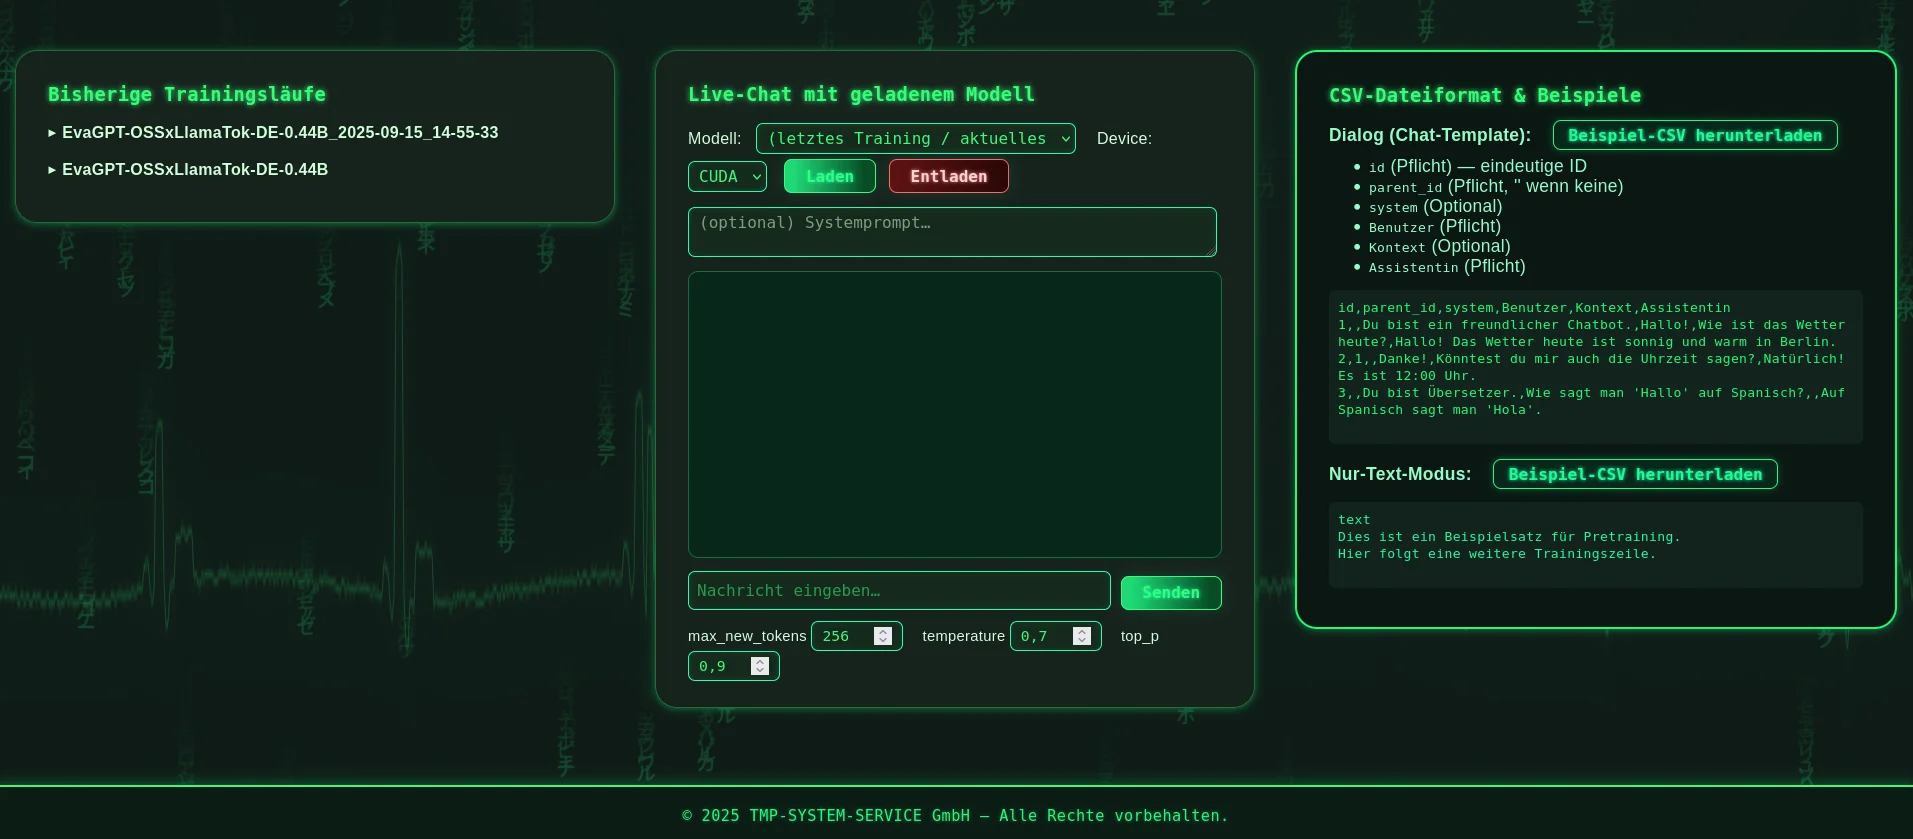
- A full web dashboard UI for controlling model training and chatting with the model
- Streaming chat endpoint with live responses
- File and Directory Initialization
- os.makedirs("./training_outputs", exist_ok=True)
- os.makedirs("./datasets", exist_ok=True)
Ensures required directories (training_outputs, datasets) exist for storing models and training data.
Web Server Initialization with FastAPI
app = FastAPI()
Uses FastAPI to define a RESTful and WebSocket-based server.
Includes:
CORS Middleware (allows access from any origin)
Mounts static files for serving model outputs
Core Functionalities
Training Configuration & Status
training_config = {...}
training_status = {...}
training_config: Default hyperparameters and paths
training_status: Shared state tracking progress, ETA, logs, and previews
Thread Safety
training_lock = threading.Lock()
Ensures that only one training session runs at a time.
Helpers and Utilities
System and File Utilities
get_hardware_info() → Collects CPU/GPU availability
get_system_status() → Retrieves memory and usage statistics
get_new_output_dir() → Creates a timestamped output folder
unload_torch_objects() → Frees GPU/CPU memory by deleting Torch objects
N-gram Handling
- Code Detection Heuristic
is_code_ngram(text)
Detects whether a text snippet is likely code, boosting its frequency during n-gram selection.
- Frequent & Diverse N-Grams
find_frequent_ngrams_diverse(...)
Extracts frequent n-grams from tokenized data
Prioritizes diversity
Supports code boosting and similarity filtering
- Tokenizer Optimization
optimize_tokenizer_and_add_ngrams(...)
Adds selected n-grams to tokenizer
Sets average embedding vectors based on original token embeddings
Dataset Iterators
Provides several iterator functions to parse and stream training samples from CSV datasets:
dialogplus_block_iter: Block-based samples for every assistant reply
dialog_iter: Converts dialog trees into full chat examples
column_iter: Simple line-by-line from a single column (for pretraining)
stream_packed_chunk_generator: Converts data into fixed-size training chunks with optional overlap and padding
Training Loop
train_loop(config)
This is the core training routine:
Loads model/tokenizer
Adds special tokens and optionally optimizes tokenizer
Loads dataset in streaming fashion
Supports:
Full training
LoRA fine-tuning
Logs live statistics
Saves model and cleans memory
Web API Endpoints
GET /hardware: Returns system hardware info
GET /sysstatus: Returns CPU/GPU/RAM usage
GET /trainings: Lists completed training runs
POST /start: Starts a new training run
POST /stop: Gracefully stops ongoing training
GET /status: Returns current training state
GET /logs: Returns recent logs
GET /livepreview: Shows the current training sample
WebSocket Endpoint
@app.websocket("/ws/logs")
Pushes real-time logs to connected clients.
Model Inference (Chat)
Supports interactive chatting with the trained model.
Loading and Unloading:
POST /load_inference
POST /unload_inference
Chat:
POST /chat: Normal chat generation
POST /chat_stream: Streaming chat (live token generation)
Web Dashboard UI
Served via the GET / endpoint.
Features:
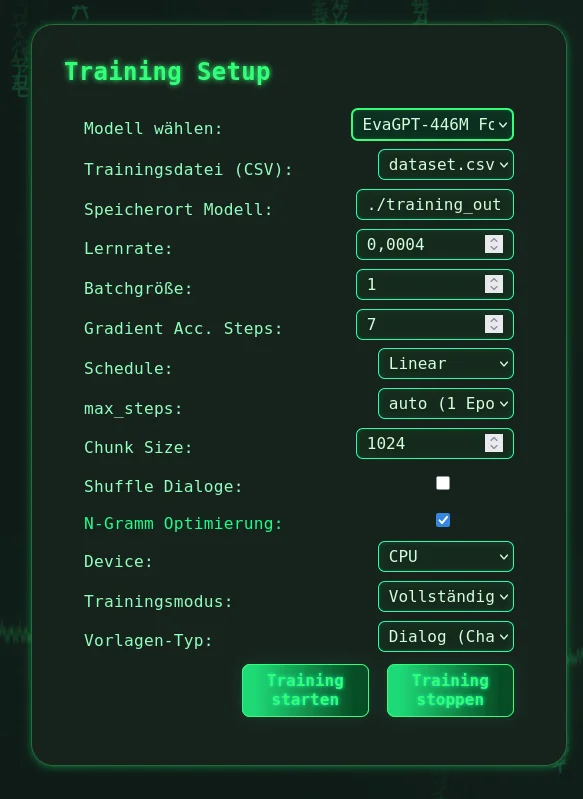
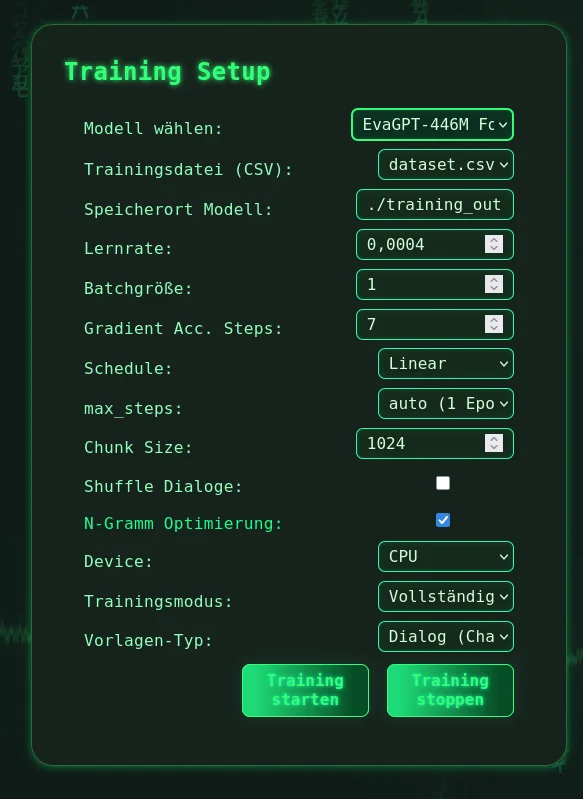
- Full control of training settings
- Resource monitoring (GPU/CPU)
- Live loss charts
- Log and preview window
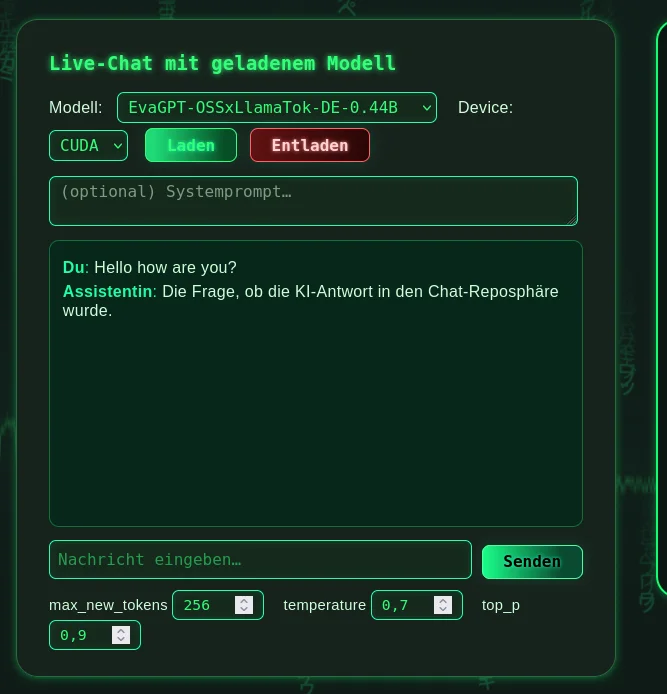
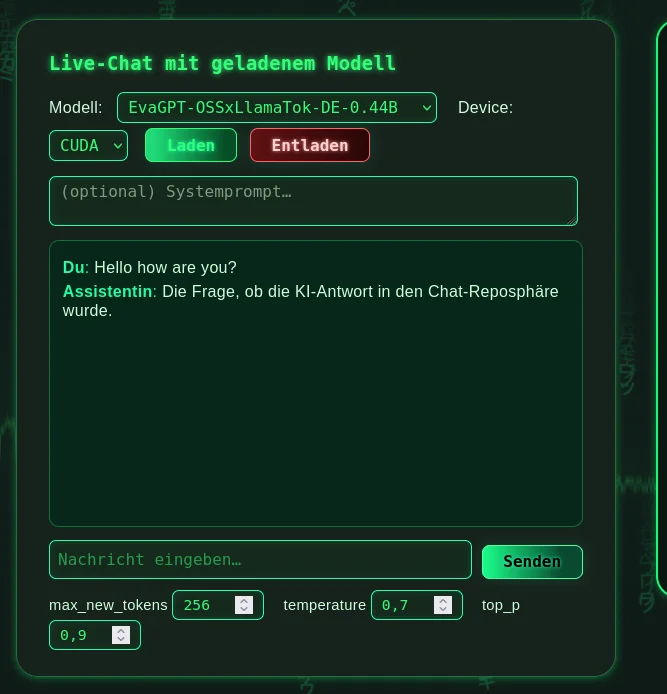
- Chat interface with the model
- Dropdowns to select model/dataset
The HTML and CSS build a modern green-themed "Matrix-style" interface.
Special Notes
Uses torch, transformers, datasets, and peft libraries
GPU and MPS support
Embedding average logic ensures newly added tokens are meaningful
Supports templates like chat, dialogplus, text for flexible formats
Modularity & Extensibility
The code is highly modular. You can:
Add new training strategies
Extend the UI
Switch from HuggingFace Transformers to other backends
Add more analytics to the live dashboard
Features
✅ Main Features Overview
🧠 LLM Fine-Tuning Platform
Full support for training and fine-tuning large language models (LLMs)
Compatible with HuggingFace Transformers, LoRA (Low-Rank Adaptation), and custom templates
Works with chat-style dialogs, block templates, and plain text datasets
📊 Web-Based Training Dashboard
Beautiful Matrix-inspired UI with real-time feedback
Configure:
Model directory
Dataset (CSV)
Training mode (full or LoRA)
Optimizer settings (learning rate, batch size, etc.)
Training chunk size and step limits
Monitor:
Live loss chart
Token preview
System resource usage (CPU, RAM, GPU)
ETA & current step
🧠 Tokenizer Optimization & N-Gram Injection
Automatically finds frequent and diverse n-grams
Detects and boosts code-like phrases
Adds n-grams as custom tokens with average embeddings
Improves efficiency for structured text and code-heavy datasets
🧾 Flexible Dataset Handling
CSV-based dialog training with threaded
id/parent_idSupports:
Chat format with user/assistant turns
Block training: trains on each assistant reply separately
Plain text training (single column)
Streaming, chunked data loading with overlap and context windowing
🛠️ Advanced Training Engine
Based on HuggingFace's Trainer API
Includes:
Gradient accumulation
Learning rate schedulers (linear, cosine)
GPU (CUDA) and Apple MPS support
Checkpoint saving
Dynamic max_steps calculation
Supports LoRA fine-tuning with PEFT module
📡 Live Training API
REST + WebSocket API
Real-time access to:
Training status
Logs
System usage
Token preview
Allows starting and stopping training via API
💬 Interactive Chat Interface
Load trained model and chat directly via web UI
Includes:
Streaming response mode
System prompt support
Sampling controls:
temperature,top_p,top_k, etc.
Auto-detects special tokens (
<|System|>,<|Benutzer|>,<|Assistentin|>)
🧰 System Monitoring
Shows:
CPU utilization
RAM usage
GPU model, memory, and usage
Number of CUDA GPUs
Visualized via custom animated gauges and EKG background
📁 Training Run Management
Each training run saved in a timestamped folder
Includes
config.jsonfor reproducibilityPast runs visible in dashboard with config download
💡 Developer-Friendly Design
Modular structure
Easily extensible with new templates, datasets, and models
Clean Python + FastAPI backend
Live preview of training samples and token masks
$ 99
- Verified source code
- Join 35191+ buyers which trust us!
- Download code immediately

100% Guarantee For Item!
Satisfaction guarantee policy.
Satisfaction guarantee policy.
Information
| Category | Scripts & Code / Python |
| First Release | 16 September 2025 |
| Files included | .html, Javascript .js |
| File Size | 1 MB |
| Frameworks | Python |
Similar Items